News & Insights

Discover the latest news, insights, and updates from ISODS

ISODS Special Citation: Recognizing OpenAI’s Research Team for Innovations in Formal Mathematics

ISODS Special Citation: Recognizing OpenAI’s Research Team for Innovations in Formal Mathematics

The International Society of Data Science (ISODS) is pleased to award a Special Citation of Merit to the Reasoning Research Team at OpenAI. This honor recognizes their groundbreaking work in AI-driven mathematical discovery, particularly their use of extended test-time compute to generate machine-verified formal proofs using the Lean interactive theorem prover.
Announcing the ISODS Index: A Public Directory of Data Science & AI Programs

Announcing the ISODS Index: A Public Directory of Data Science & AI Programs

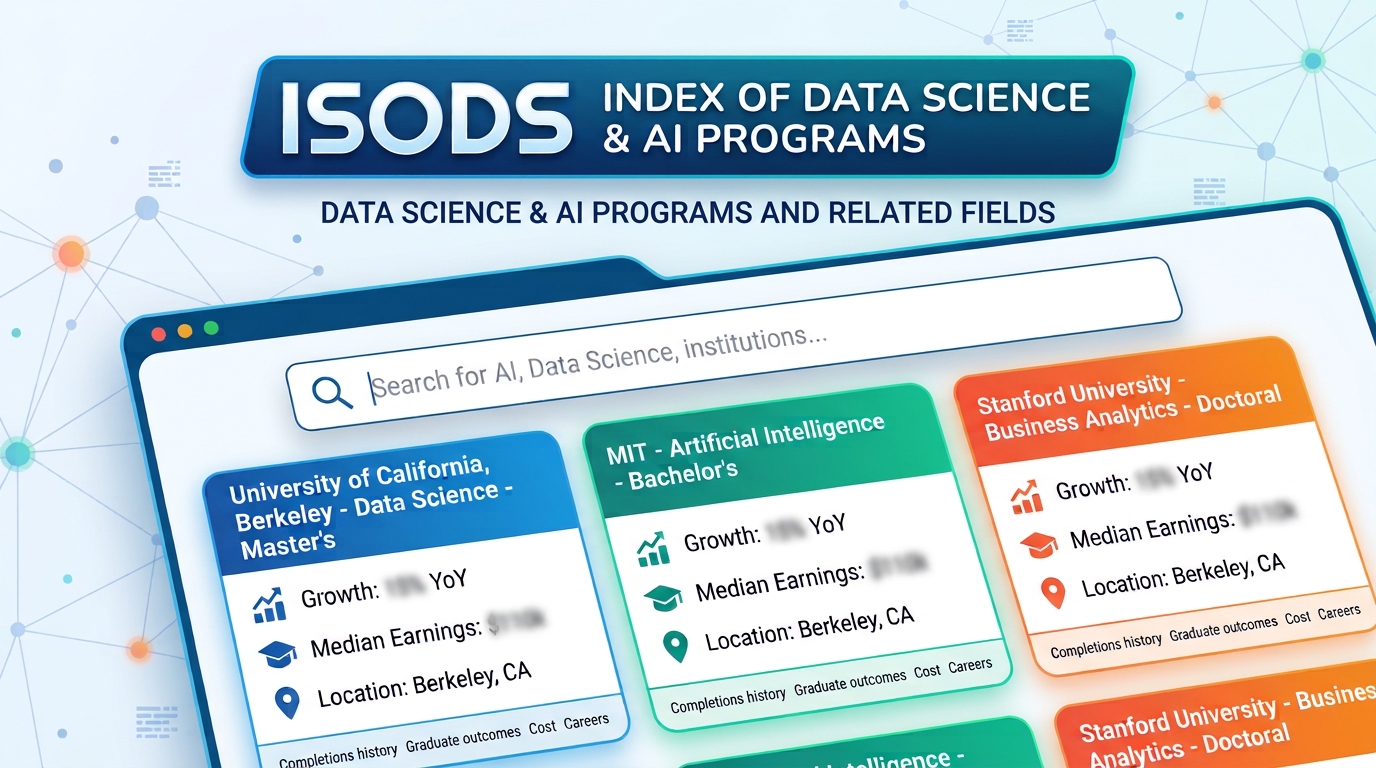
ISODS is pleased to announce the ISODS Index of Data Science & AI Programs, a public catalog of degree programs in data science, artificial intelligence and related fields. The index is live today at /catalog.
Collaboration Between ISODS and Vietnam

Collaboration Between ISODS and Vietnam

The International Society of Data Scientists (ISODS) have established a formal collaboration with Vietnam to co-develop, standardize, and deliver advanced training programs in artificial intelligence, cybersecurity, and data science. 

AI & Data Science Headlines

Curated headlines from AI, ML, and data science sources around the web

via arXiv cs.AI

HybridSpec: Throughput-Aware Speculative Decoding for Hybrid GDN-MoE Models

arXiv:2611.04055v1 Announce Type: new Abstract: In speculative decoding, parallel drafters such as DFlash make drafting cheap, so target verification dominates each round. A central choice is the verification length, the number of tokens that the target processes in each round. Verifying more draft tokens can accept more of them, but work after the first rejection is wasted. For hybrid target models that combine Gated DeltaNet (GDN) and mixture-of-experts (MoE) layers, verification time grows…

arXiv cs.AI

via arXiv cs.AI

Forgetting to Improve: Principled Data Removal in Active Learning

arXiv:2611.04054v1 Announce Type: new Abstract: The uncertainty of a statistical model is most commonly factorized into an aleatoric and an epistemic part. This factorization changes how predictions are interpreted in downstream decision tasks. Importantly, except for the idealistic scenario with no model mismatch, the quantification is a characteristic of the model and not the data generating process. In this paper, we propose Forgetting to Improve a method that reduces this discrepancy by…

arXiv cs.AI

via arXiv cs.AI

Exploit or conform? How norm utility prompting changes the way LLMs use community beliefs

arXiv:2611.04048v1 Announce Type: new Abstract: Large Language Models (LLMs) serve both as tools for aiding human decision-making in everyday life and as models of human agents in experimental simulation studies. Alignment on prototypical social decisions -- such as whether to cooperate on a collective action -- therefore has immediate practical consequences for researchers and for society at large. Here we systematically explore the impact of ``norm utility'' -- the non-material components of…

arXiv cs.AI

via arXiv cs.AI

Recursa: Toward Recursively Self-Improving Foundation Model Systems

arXiv:2611.04035v1 Announce Type: new Abstract: Foundation models in changing environments can encounter unfamiliar domain knowledge that their original training did not cover. However, new domains rarely provide large amounts of expert-created training data or reliable supervisory signals for further training. We introduce Recursa, a foundation model system that adapts to new domains by learning from its own experience without human experts or a stronger teacher model. Recursa uses a knowledge…

arXiv cs.AI

via arXiv cs.AI

ROCm InferaSim: Cut LLM Serving Trial Costs and Deploy the Best Configuration

arXiv:2611.04032v1 Announce Type: new Abstract: Serving an LLM efficiently depends on the engine, how the model is split across GPUs, precision, scheduler settings, speculative decoding, KV-cache management, and prefill-decode disaggregation. The best configuration depends on the model, hardware, workload, and objective. Operators usually find it by trial and error. Exhaustively measuring the candidates in our study would take about 25,000 GPU-hours. ROCm InferaSim predicts serving performance…

arXiv cs.AI

via arXiv cs.AI

Controlling Action-Head Co-Adaptation to VLM Representation Anisotropy

arXiv:2611.04006v1 Announce Type: new Abstract: Modern learning systems increasingly combine pretrained models with downstream heads. Despite the growing importance of such modular designs, how the downstream model co-adapts to the geometry of pretrained representations remains relatively underexplored. We study this problem through vision-language-action models (VLAs), where a pretrained vision-language model (VLM) conditions an action model for control. We find that the action model…

arXiv cs.AI

Stay up to date

Get the latest AI and data science news delivered to your inbox.

© 2026 ISODS. All rights reserved.